Back to Projects
Completed Project
Asai (அசை) — Tamil-Oriented Language Model Tokenizer
Tamil-oriented tokenizer for language-model applications, focused on linguistic structure, morphological rules, and efficient subword representation.
|
RoleCreator & Maintainer
Timeline2024
TeamOpen Source (MIT)
Tech Stack6 Technologies
Mission Brief
Asai is an MIT-licensed Tamil tokenizer built to solve token explosion and inefficiency for Dravidian languages in Transformer models. By incorporating native Tamil morphological syllable structures and linguistic agglutinative grammar, Asai provides superior compression ratio and representation efficiency compared to standard BPE/WordPiece tokenizers.
Key Features
Linguistic Synergy
- Built on classical and modern Tamil agglutinative grammar.
- Substantially lower fertility rate compared to multilingual LLM tokenizers.
- Significantly reduces inference cost and memory for Indic NLP applications.
Open Source Ecosystem
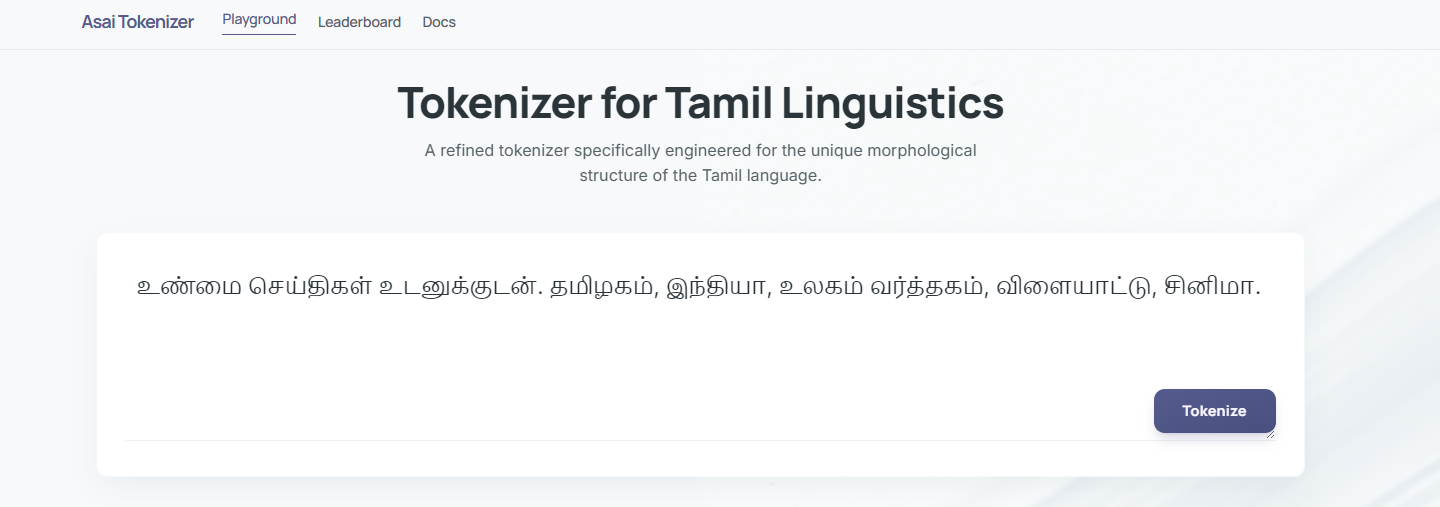
- Available on Hugging Face Spaces with interactive syllable visualizer.
- Exportable to HuggingFace Tokenizers library format for seamless integration into PyTorch models.
Visual Gallery
IMG_01
Project Access
Technologies
Python
Hugging Face
Tokenizers
Linguistics
Indic-AI
Transformers
Table of Contents
- • Mission Brief
- • Key Features
- • Visual Gallery
Back to Projects