Back to Projects
Completed Project
Hierarchical KV Cache Clustering for Memory-Efficient Transformer Inference
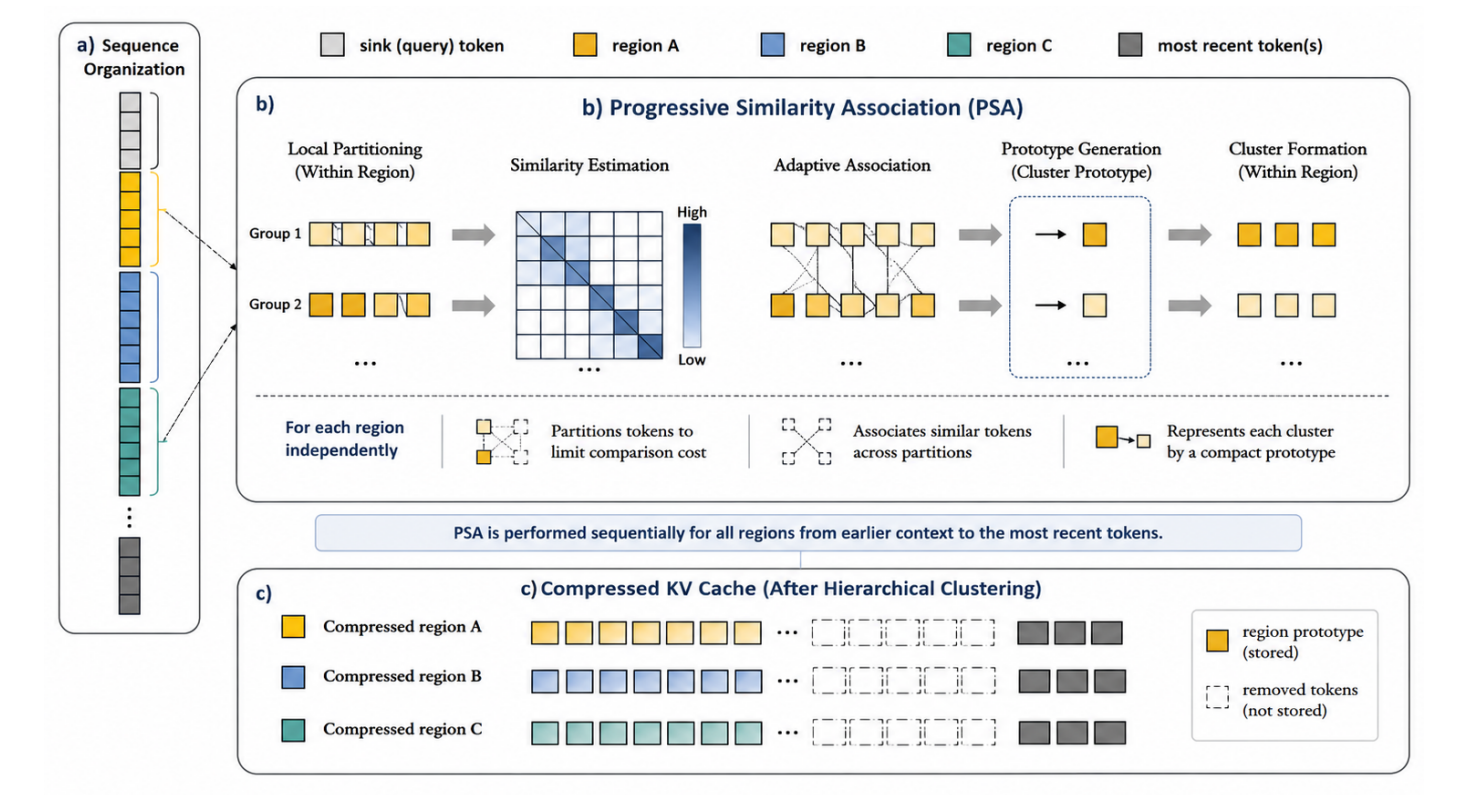
Online compression framework based on localized processing regions and Progressive Similarity Association (PSA). Up to 83% memory reduction and 4.3x throughput.
|
RoleLead AI Researcher & Author
Timeline2025 - 2026
TeamResearch Project
Tech Stack6 Technologies
Mission Brief
A breakthrough research study on memory-efficient Transformer inference, specifically tackling the massive memory footprint of the Key-Value (KV) cache during long-context autoregressive generation. Proposes an online compression framework based on localized processing regions and Progressive Similarity Association (PSA). Experiments report up to 83% KV-cache memory reduction, up to 2x autoregressive inference speed improvement, and up to 4.3x serving-throughput improvement without significant perplexity degradation. Published on ResearchGate with DOI 10.13140/RG.2.2.11098.09927.
Key Features
Progressive Similarity Association (PSA)
- Clusters attention KV representations dynamically during long-context decoding.
- Preserves critical contextual tokens while compressing redundant historical state.
- Maintains generation perplexity within nominal error bounds.
Hardware & Inference Benchmarks
- Evaluated across LLaMA, Mistral, and Transformer backbones.
- Substantial reduction in GPU VRAM requirements enabling longer context lengths.
- Empirical validation published with full mathematical derivation and metrics.
Visual Gallery
IMG_01
Project Access
Technologies
PyTorch
Transformer Architecture
KV-Cache Optimization
CUDA
Python
ResearchGate
Table of Contents
- • Mission Brief
- • Key Features
- • Visual Gallery
Back to Projects